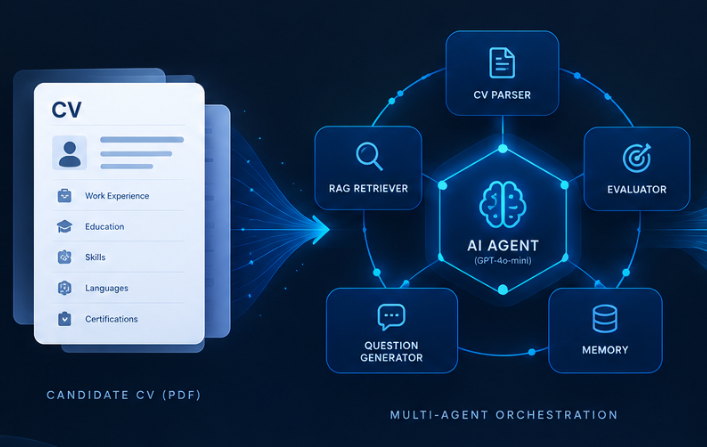
AI Talent Intelligence System
Enterprise-grade multi-agent RAG platform combining vector retrieval, persistent memory, and LLM orchestration (GPT-4o-mini) to automate candidate CV parsing, evaluation, and question generation.
With a Bachelor’s in Biology and a Master’s degree in Data Science, I bridge domain knowledge with robust engineering. I build scalable ETL/ELT data pipelines, optimize database schemas, and deliver clean, reliable data architectures that empower data-driven decision making.
Data Projects
Data Reliability Focus
Core Technologies
Combining scientific rigor with modern data engineering tools to build reliable, high-volume data ecosystems.
Designing, automating, and monitoring batch and streaming data processing workflows with high reliability.
Architecting relational, star-schema, and dimensional data models optimized for fast query performance.
Transforming complex datasets into executive dashboards, KPIs, and interactive reporting tools.
How I design and structure scalable data operations from raw source ingestion to final business intelligence.
APIs, Web Scrapers, Relational DBs & External Flat Files (CSV, Parquet, JSON)
Data cleaning, schema alignment, data quality checks & enrichment via Python & SQL
Relational Databases, Data Warehouses & Star-Schema Dimensional Models
Interactive Power BI Dashboards, Executive Reports & Downstream Analytics
Explore selected data engineering pipelines, AI RAG systems, database optimization, and BI analytics.
Enterprise-grade multi-agent RAG platform combining vector retrieval, persistent memory, and LLM orchestration (GPT-4o-mini) to automate candidate CV parsing, evaluation, and question generation.
SQL data analysis evaluating country-level deforestation data globally. Structured relational queries to uncover environmental impacts and area loss trends over time.
Re-engineered and normalized an inefficient database schema for a social news platform. Fixed data integrity issues, implemented constraints, and added user web analytics using SQL.
Data extraction and correlation analysis pipeline examining variables affecting movie box-office revenue using Python, Pandas, NumPy, and Seaborn heatmaps.
Comprehensive financial data model and interactive Power BI report for Seven Sages Brewing Company. Enables executive leadership to analyze beer margins and product profitability.
Data cleaning and transformation pipeline analyzing global infection and mortality trends across countries and continents using Python, NumPy, Pandas, and Matplotlib.
Product intelligence dashboard comparing device adoption and telemetry metrics between dog and cat smart collar lines for startup commercial strategy.
Targeted marketing analytics and segmentation report for an e-commerce apparel company, guiding advertising spend toward high-ROI product categories.
Automated Python web scraper built with BeautifulSoup that monitors product availability, logs price fluctuations into CSV storage, and alerts on price drops.
Whether you have a data engineering role, a pipeline project, or a database query optimization task in mind, feel free to reach out!